There is No Hyperparameter Free Algorithm
Published:
We are always hyperparameter tuning.
Yet, a quick scroll through arXiv will soon lead to you to a menagerie of “hyperparameter-free” algorithms.
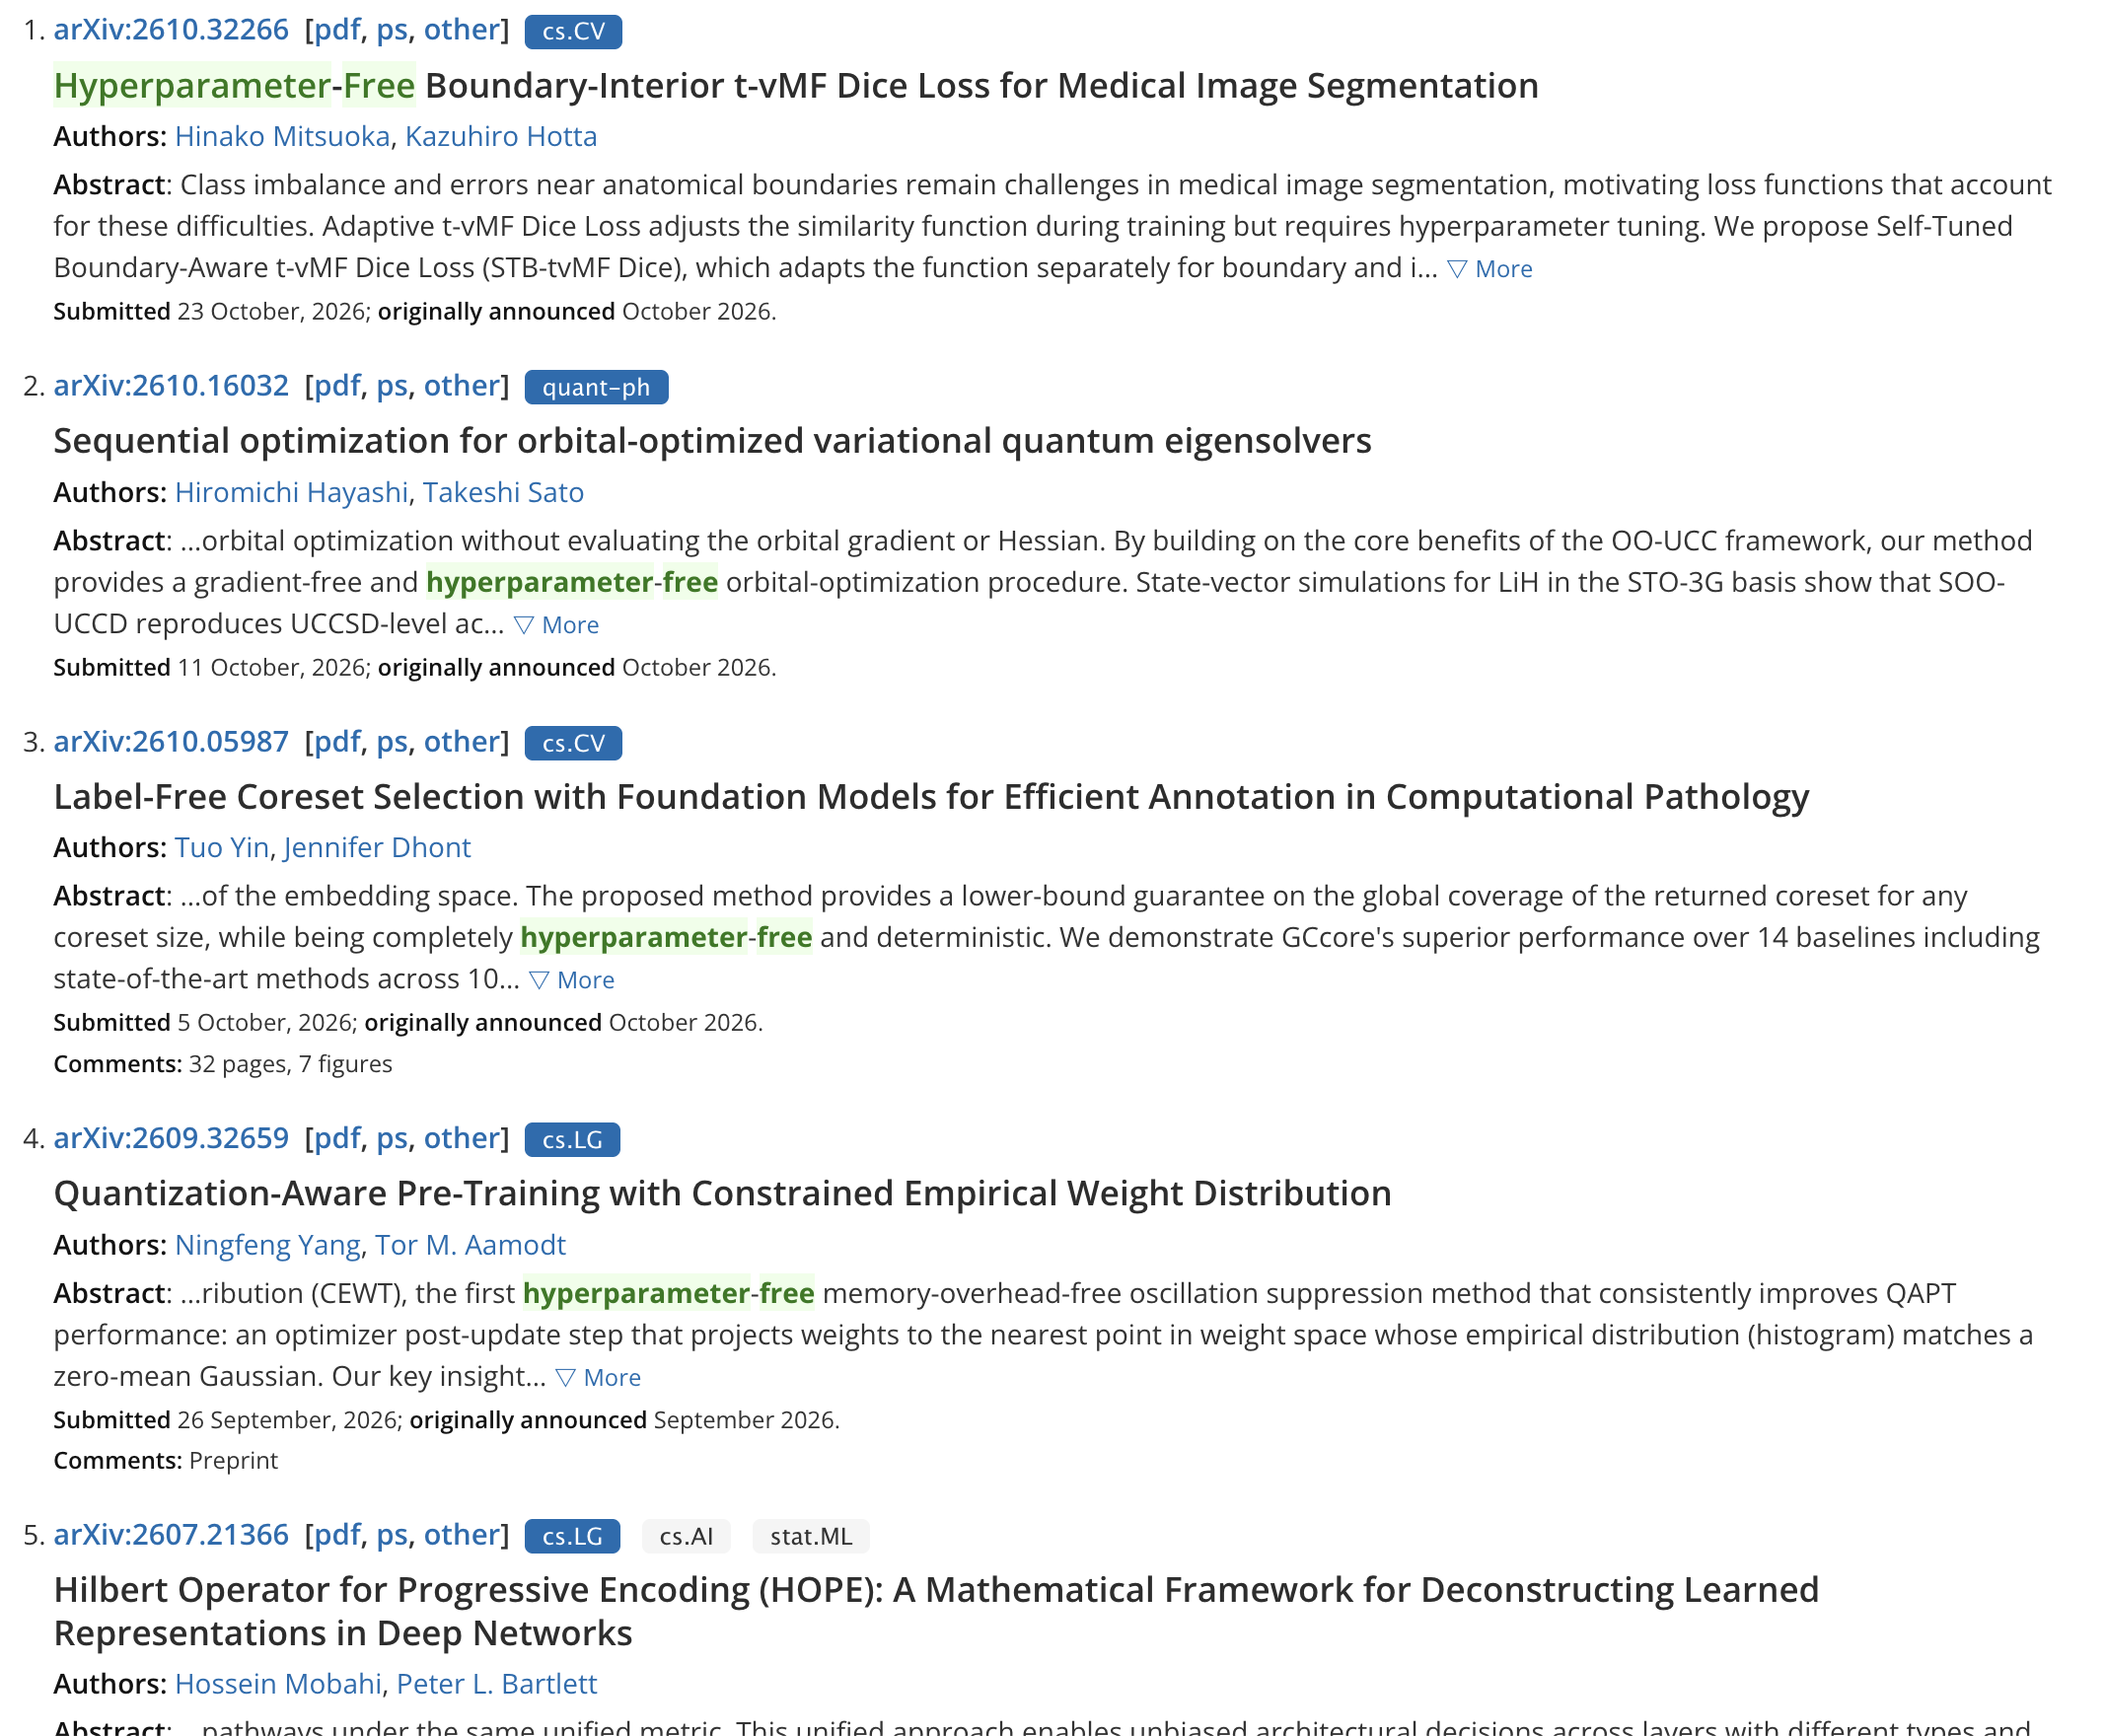
What does such a phrase even mean, and is it even possible? I don’t think so, and hopefully I can convince you that it isn’t.
What is a Hyperparameter?
A hyperparameter is a number which controls some aspect of how an algorithm is run, and is set in advance of running said algorithm. If that sounds vague, it’s because it is. Confusingly, some fields refer to hyperparameters as parameters. The “hyper-“ prefix arises from machine learning, where the weights in neural networks are frequently referred to as parameters, so the hyperparameters are parameters controlling parameters. We’ll stick with hyperparameters to make the distinction clear, although I would argue that there really isn’t one.
For a concrete example, let’s say I want to build a neural network to classify if an email is spam or not spam. A simple example of a hyperparameter is how many layers the network should have. Another example is perhaps the number of neurons, the width, in each layer.
Since model architecture and optimization algorithms are frequently considered in tandem, another example of a hyperparameter would be the stepsize (or learning rate) of your chosen variant of stochastic gradient descent. Even more subtely, the choice of random seed is also a popular hyperparameter to analyze and tune.
Hyperparameters come up in a lot of other fields, even if we don’t realize it, or even if the place it appears is not necessarily considered an algorithm. For example, the choice of $p = 0.05$ common in many statistical tests of significance is a hyperparameter. The algorithm in question here is the decision rule to reject or fail to reject the null hypothesis. The algorithm takes in some data, computes some statistics, evaluates their associated significance level (the mythical $p$-value), and based on a preset threshold, decides to reject or fail to reject the null hypothesis (setting the significance level before collecting the data is critical!). The choice of such a threshold is a hyperparameter. It may not necessarily be one that the user gets to decide for themselves (we seem to have coalesced around using $p=0.05$ for everyone), but it is a number that guides the trajectory of our algorithms, set in advance of running said algorithm.
Hyperparameter-Free Algorithms
The promise of hyperparameter-free algorithms is that they can bypass the need to tune hyperparameters, and instead compute the optimal (or good enough) value of the hyperparameter as a function of the input. The user of the algorithm doesn’t need to do anything except press start.
A very simple example of a seemingly hyperparameter-free algorithm is Gaussian elimination. This algorithm takes as input a $m\times n$ matrix $A$ and an $m$-vector $b$, and returns a $n$-vector $x$ which satisfies $Ax = b$, or states that no such $x$ exists. The algorithm can be recursively described very simply: divide the 1st row by the top left entry $a_{1,1}$ so that the top left entry is 1 (if $a_{1,1} = 0$ we have to do a pivot). Then, for each row $a_{i,:}$, set $a_{i,:} \leftarrow a_{i,:} - a_{i,1}a_{1,:}$. This makes the first column of the matrix all zeros except for the top entry, $a_{1,1} = 1$.
At first glance, Gaussian elimination has no hyperparameters. Moreover, this algorithm works great in practice. The only reason you might not want to use Gaussian elimination is if your matrix is so big that moving it in and out of memory causes significant bottlnecks. The devil is in the details however. The choice of a pivot is a hyperparameter that can significantly affect the performance of the algorithm. There are a lot of good ways to do pivoting, and they have good performance in practice, but it is still a choice that one must make before running the algorithm. Making such a choice isn’t even necessarily a bad thing: choosing hyperparameters well can bring significant performance benefits without the hassle of trying to compute the hyperparameters on the fly.
One can see another analogy in the simplex algorithm. A priori it doesn’t appear to have any hyperparameters to tune, but the various mechanics of pivoting and quickly solving the linear system in the next basis lead to significant performance differences. For a broader example of the same idea, Ben Recht has great lecture notes about why convex programming is not yet free from the banality of tuning.
The Social Aspect
There is a persistent drive in all fields of human activity to remove humans from the equation. The use of cost-benefit analyses, randomized clinical trials, model-free control, and many other “plug-and-play” algorithms promise to release us from having to make decisions. This is highly enticing. After all, humans are complicated and messy, and algorithms are very obedient. Their allure lies in the explicit instructions they follow and their impartial facade. One might imagine that we could enumerate the factors that we want to consider, have an algorithm take these into account, and simply press start and have these taken care of for us. Unfortunately, the obedience of algorithms to their human creators is precisely the issue. Even if we hope that a particular design choice will help us avoid the effort or responsibility of making a decision, every algorithm contains hyperparameters and hidden assumptions that its user must (or at least should) be aware of before running.
To be clear, algorithmic decision-making is not a bad practice. In fact, its often superior to the equivalent human decision. The trouble is that “superior” means a very particular thing, and it may not be the metric we are truly interested in. The benefit of algorithms is that they can make our interests and assumptions (or lack thereof) explicit, rather than the implicit nature of human-decision making. It is up to us to be aware of what hyperparameters we implicitly select when we use these tools.